Web Scraping Without Getting Blocked in 2026: 10 Anti-Bot & IP Rotation Strategies
Learn how to run web scraping without getting blocked in 2026 using rotating residential proxies, TLS fingerprint spoofing, HTTP headers, and rate limiting.
Learn how to run web scraping without getting blocked in 2026 using rotating residential proxies, TLS fingerprint spoofing, HTTP headers, and rate limiting.
Web scraping, the process of extracting data from websites, can often feel like a quest for valuable information not readily available through APIs. However, like any worthwhile quest, it comes with its challenges, primarily encountering access blocks imposed by target websites. These blocks can result from stringent scraping policies, concerns over resource abuse, IP reputation issues, or the detection of non-human user agents. But don't worry; this guide will help you navigate web scraping while minimizing the risk of getting blocked, all thanks to strategic use of tools like ProxyTee.
Strategies to Avoid Access Blocks
Effectively avoiding access blocks often requires implementing a combination of techniques. Let's explore strategies you can use with ProxyTee's Residential Proxies to minimize the risk of being blocked.
1. Understand Your Target’s Policies and Terms of Service
Before scraping a new website, it’s crucial to understand its terms of service and scraping policies. This understanding often involves determining if the site permits scraping, and which sections you can access. Ignoring these rules can lead to blocking and potential legal risks. Pay close attention to the robots.txt file found in the root directory of the website, which gives instructions on which areas web robots shouldn’t crawl.
Here’s an example of a robots.txt file:
User-agent: *
Disallow: /private/
Disallow: /temp/
This file commands all web robots (* after User-agent) to steer clear of the site's private and temp directories. Ethical scraping is all about respecting website guidelines.
2. Adhere to Ethical Scraping Standards
Following ethical guidelines is just as important as respecting a website’s formal policies. This practice not only prevents blocks, but it also respects the website’s resources and rights. Some crucial considerations include:
- Avoid Server Bombardment: Put ample time delays between your requests to prevent overwhelming servers. Avoid quick, excessive requests that are uncharacteristic of normal human behavior. Incorporating irregular intervals using tools from ProxyTee makes your traffic less distinguishable from legitimate human traffic.
- Do not Scrape Personal Data without Consent: Only extract personal data with proper permissions, and be wary of legal consequences and ethical concerns.
- Respect the Data You Obtain: Always handle scraped data responsibly and in compliance with regulations like GDPR.
Here is a sample of how you can implement random intervals using Python:
import time
import random

urls = ['https://www.targetwebsite.com/page1', 'https://www.targetwebsite.com/page2', 'https://www.targetwebsite.com/page3']

for url in urls:
    response = requests.get(url)
    # Process response
    sleep_time = random.uniform(1, 10)  # Generate a random sleep time between 1 and 10 seconds
    time.sleep(sleep_time)  # Sleep for a random time between requests
This snippet randomly pauses the program, making it look more like human navigation, and minimizing the chances of detection.
3. Leverage Rotating Proxies from ProxyTee
Proxies, specifically rotating proxies like those offered by ProxyTee, are essential for web scraping. Residential Proxies from ProxyTee act as a gateway, masking your IP address by making requests from diverse locations. Instead of a single IP, rotating proxies uses a pool of IPs. This approach makes it significantly more difficult for target websites to pinpoint and block your scraper.
Additionally, with its Auto Rotation feature, ProxyTee ensures that your requests come from a variety of IPs and greatly decreases the chance of one being banned for too many requests. Here's a quick demonstration:
import requests
from itertools import cycle

# List of proxies provided by ProxyTee
proxy_list = ['ip1:port1', 'ip2:port2', ...]
proxy_pool = cycle(proxy_list) # create a cycle of proxies

url = 'https://www.targetwebsite.com'

for i in range(1,3):
    # Get a proxy from the pool
    proxy = next(proxy_pool)
    print(f"Request #{i}:")
    try:
        response = requests.get(url, proxies={"http": proxy, "https": proxy})
        print(response.content)
    except:
        # Most free proxies will often get connection errors, so we catch them here
        print("Connection error with proxy:", proxy)
By using a rotating set of IPs from ProxyTee, your scraper’s operations will become much harder to identify. However, remember to implement these as part of a larger strategy for a successful scraping campaign.
4. Use the Right Headers and User Agents
Websites utilize user agents and headers to identify bots. A User-Agent header is provided by the browser, providing specifics like software, OS, and vendor info that is key to detecting bot behavior. You can mimic an actual user and avoid blocks by using legitimate user agent strings, especially if these vary.
Besides User-Agent, the Referer header provides information on the URL of the previous page linked to the one you requested. This further adds a human touch to your scraper. By adding other common web browser headers such as Accept-Language, Accept-Encoding, and Connection, you add credibility to your request.
Here is an example of how this can be used:
url = 'https://www.targetwebsite.com'
headers = {
    'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/112.0.0.0 Safari/537.36',
    'Referer': 'https://www.google.com/'
}

response = requests.get(url, headers=headers)
5. Handle Honeypot Traps and Errors
Websites may use honeypots to target bots by incorporating hidden links, so be mindful of HTML elements with style set to hidden or none. These are invisible to regular users but visible to bots. Using a web scraping tool like BeautifulSoup allows your code to bypass such links:
from bs4 import BeautifulSoup
import requests

url = 'https://www.targetwebsite.com'
response = requests.get(url)
soup = BeautifulSoup(response.text, 'html.parser')

for link in soup.select('a'):
    if 'display' in link.get('style', '') and 'none' in link['style']:
        continue  # Skip this link
    # Process link
Also pay attention to the status codes; 4xx represent client errors, while 5xx indicate server errors. When faced with 4xx or 5xx errors, consider implementing exponential backoff algorithms. By progressively delaying your request retries, you are being more respectful of website resources.
6. Consider a CAPTCHA Solving Service
CAPTCHAs, used to deter bots, can pose a huge challenge to scraping. Consider integrating a service, such as ProxyTee’s human solver functionality which, combined with machine learning algorithms, quickly deciphers CAPTCHAs. Using a CAPTCHA solving service makes your data extraction smooth by effectively dealing with bot detection techniques. You might find useful integration tools within the API offered by ProxyTee.
7. Monitor Rate Limits and Access Denials
To preserve server integrity and prevent resource abuse, many websites have rate limitations in place. The limits, shown in X-RateLimit-Limit, often result in HTTP status codes, which means you must adjust your scraper behavior. Usually, a 200 status code means everything went correctly, 429 indicates you have sent too many requests, 403 means access is restricted, and 503 indicates the server is overwhelmed. With ProxyTee, consider an exponential back-off algorithm:
import time
import requests

def respectful_requester(url, delay_interval=1):
    response = requests.get(url)
    # If the status code indicates rate limiting, sleep then retry
    if response.status_code == 429:
        print('Rate limit reached. Sleeping...')
        time.sleep(delay_interval)
        return respectful_requester(url, delay_interval)
    elif response.status_code != 200:
        print(f'Error: {response.status_code}. Try a different proxy or user-agent')

    return response
This function adjusts its delay interval, responding to any rate-limiting codes by adding sleep time. Consider exploring ProxyTee’s pricing page to get cost-effective solutions for your business.
8. Scrape from Google’s Cache
Scraping from a cached copy is ideal for difficult websites, especially when dealing with data that doesn’t have to be very up-to-date. To access the cached content, add the website’s URL to the end of http://webcache.googleusercontent.com/search?q=cache: . This alternative allows scraping without triggering anti-scraping measures. However, some websites instruct Google not to cache their data, and cached data may not be recent.
9. Vary the Request Pattern
Websites become suspicious if the scraping pattern is too predictable. By varying requests with random pauses and different request orders (achieved using Python's random and time libraries), you can mimic human behavior. Tools such as Selenium or Puppeteer can simulate user behavior further by clicking around and completing forms. Making requests as erratic and random as a user helps you stay under the radar.
10. Use Third-Party Proxies and Scraping Services
Because of increasing sophistication, a third-party like ProxyTee, might offer a good alternative to an in-house scraper solution, which is usually complex and difficult to maintain. ProxyTee, for example, is constantly updating its techniques in order to stay ahead of bot-detection mechanisms. These techniques enable their Unlimited Residential Proxies and automatic CAPTCHA solutions to be effective in your data scraping efforts.
Conclusion
The path to successful web scraping requires navigating many roadblocks. Now that you are better acquainted with handling various challenges such as website policies, ethics, using ProxyTee's rotating proxies, adjusting user agents and headers, handling honeypot traps, and managing rate limits, you are much more equipped to conduct web scraping. Remember that a solid toolbox can be valuable. Services like ProxyTee give you a broad selection of services to help streamline your projects. With features like unlimited bandwidth, global coverage, and multiple protocol support, you can avoid detection. In addition, using the ProxyTee API provides robust control over your operations. Take your scraping to the next level with ProxyTee!
Configuring Proxies for Market Research & E-Commerce Intelligence in 2026
When enterprise teams deploy proxies for market research, dynamic price monitoring, or competitive market intelligence, avoiding IP bans requires synchronizing three layers of your scraping stack:
- Layer 1 — Network Identity (Rotating Residential IPs): Route requests through real household ISP connections across 100+ countries so target WAFs (Cloudflare, Akamai, PerimeterX, DataDome) see organic consumer traffic.
- Layer 2 — TLS & HTTP Header Hygiene: Align your
User-Agent,Sec-Ch-Uaclient hints, and TLS JA3/JA4 cipher suites using Playwright, Puppeteer Stealth, or cURL custom HTTP headers. - Layer 3 — Session & Rate-Limit Orchestration: Match your 3 to 60 minute auto-rotation interval to the target site's session model—fast rotation for catalog discovery, sticky sessions for cart and localized inventory checks.
Related Anti-Bot & Web Scraping Guides
Explore our specialized tutorials on Effective Strategies for Bypassing Cloudflare, Bypassing PerimeterX Barriers, Bypassing CAPTCHAs with Playwright, and Market Intelligence Proxy Solutions.
Recommended ProxyTee Configuration & Bandwidth Benchmark
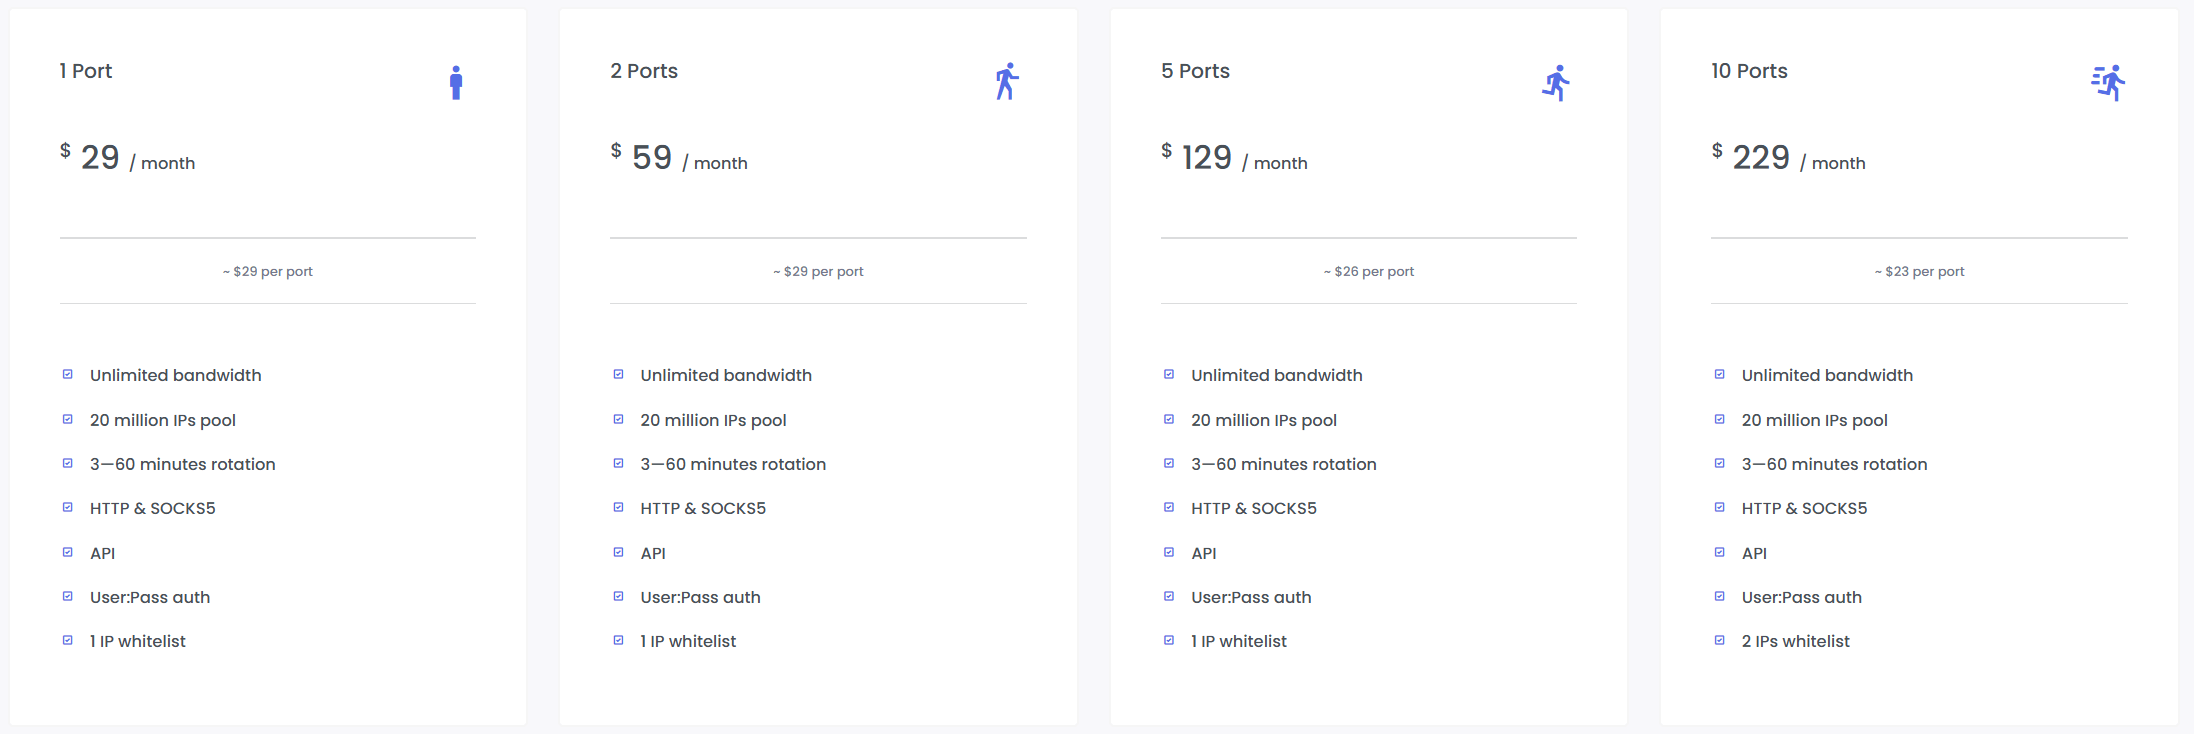
To run Web Scraping Without Getting Blocked in 2026: 10 Anti-Bot & IP Rotation Strategies reliably in production without per-gigabyte overage fees, pair ProxyTee Unlimited Residential Proxies with our DuoPlus Cloud Mobile Integration Guide and Amazon Scraping & Buy Box Proxies workflow. You can route traffic through localized household ISPs such as Switzerland Residential Proxies (640,000+ IPs) or compare flat-rate port economics in our ProxyTee vs. Nimble (Nimbleway) benchmark.
Recommended ProxyTee Configuration for Exploring
When deploying this workflow in production, matching your protocol, rotation interval, and concurrency tier to the target anti-bot posture is critical. Compare the recommended configurations below:
| Configuration Parameter | High-Throughput Scraping | Stateful Session / Multi-Account | ProxyTee Advantage |
|---|---|---|---|
| Proxy Protocol | HTTP / HTTPS or SOCKS5h | SOCKS5 with Remote DNS | Dual protocol support on every port |
| Rotation Interval | 3 to 10 minutes auto-rotation | 30 to 60 minutes sticky window | Configurable 3–60m in GUI & REST API |
| Authentication | IP Whitelisting (Server / Docker) | Username:Password per profile | Dual auth modes included free |
| Bandwidth Billing | 100% Unmetered ($0.00/GB) | 100% Unmetered ($0.00/GB) | Saves up to 95% vs metered per-GB providers |
Frequently Asked Questions
Combine rotating residential proxies (30M+ real household IPs) with realistic browser headers, TLS fingerprint alignment in Playwright or Puppeteer, and randomized request delays.
Principal infrastructure engineer at ProxyTee specializing in rotating residential proxy networks, SOCKS5/HTTP tunneling, TLS fingerprint mitigation, and distributed data extraction pipelines.