Spicrawl Web Scraping API for AI Agents & Developers: Complete Guide + ProxyTee Workflows
Discover how Spicrawl turns dynamic, JavaScript-heavy websites into LLM-ready Markdown, JSON, and HTML via REST API, CLI, or MCP server—and how it pairs with ProxyTee's unlimited residential proxies for large-scale AI data pipelines.
Explore Spicrawl's web scraping API, CLI, and hosted MCP server for AI agents and RAG pipelines, paired with ProxyTee's unlimited bandwidth residential proxies.
- •Meet Spicrawl: Web Data Extraction Built for Developers and AI Agents
- •What Can You Do with Spicrawl? Core Platform Capabilities
- •Developer Quickstart: Spicrawl REST API, CLI & MCP Setup
- •How Spicrawl and ProxyTee Power Scalable AI & Web Data Pipelines
- •Ready to Make Website Data Work for Your AI Agents?
The internet holds an extraordinary amount of structured and unstructured knowledge, yet extracting clean data from modern websites remains a persistent engineering hurdle. JavaScript-heavy single-page applications, login-gated dashboards, aggressive WAF rules, and bloated HTML DOM trees can turn a straightforward data pipeline into weeks of headless browser maintenance. Today, we are excited to welcome Spicrawl to the ProxyTee Official Technology Partner Ecosystem.
Spicrawl is a web scraping and data extraction platform purpose-built for developers, automation builders, and AI agents. Combined with ProxyTee’s 30M+ rotating residential proxies, engineering teams can reliably extract LLM-ready Markdown and structured JSON across geo-restricted or protected sites without paying per-gigabyte bandwidth surcharges.
Meet Spicrawl: Web Data Extraction Built for Developers and AI Agents
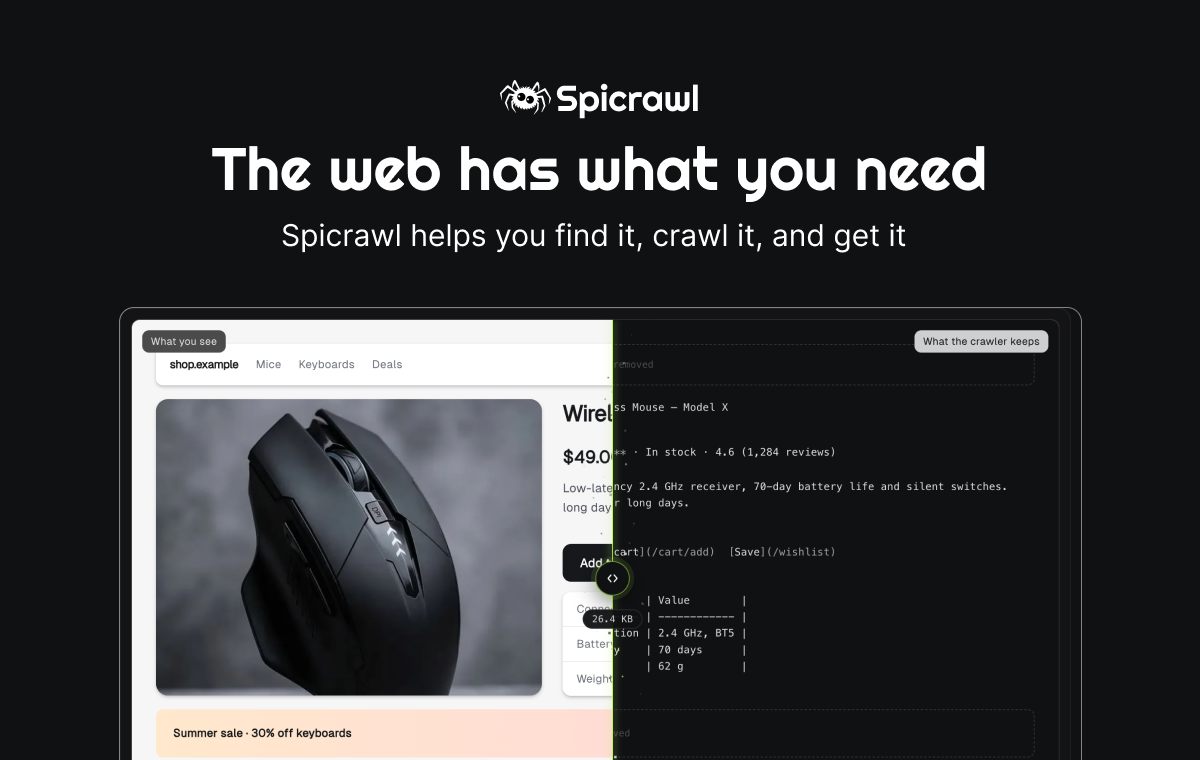
Traditional web scrapers force developers to choose between brittle HTTP parsers that break on client-side rendering and self-hosted browser clusters that consume significant CPU, memory, and operational time. Spicrawl removes that infrastructure burden behind a single REST endpoint (POST /v1/scrape), an agent-ready CLI, a TypeScript SDK, and a hosted MCP server.
With automatic engine selection (mode=auto), Spicrawl attempts a fast plain HTTP fetch first and seamlessly escalates to real browser JavaScript rendering only when a page requires it—converting cluttered HTML into clean content ready for embeddings, retrieval-augmented generation (RAG), and downstream ETL workflows.
What Can You Do with Spicrawl? Core Platform Capabilities
Whether you are building an autonomous research assistant or refreshing an enterprise price-monitoring warehouse, Spicrawl unifies extraction, interaction, and scheduling inside one developer-friendly toolkit.
1. Extract Website Data into LLM-Ready Markdown, JSON, and HTML
Send any public URL and receive clean Markdown (main content isolated from boilerplate navigation), typed JSON (via autoparse, CSS selectors, or a JSON Schema), raw HTML, plain text, full-page screenshots, or PDF captures. Built-in resource blocking and optional caching (up to 48 hours) minimize token bloat when feeding live pages into large language models.
2. Dynamic JavaScript Rendering, Browser Actions, and Persistent Sessions
Modern SaaS catalogs, travel booking portals, and interactive dashboards rely heavily on asynchronous JavaScript hydration. Spicrawl supports real headless browser rendering alongside programmable browser actions—allowing your workflow to click buttons, type queries, select dropdowns, scroll infinite feeds, or execute custom JavaScript steps before capturing the final DOM. Persistent sessions carry cookies and browser storage across consecutive requests so authenticated multi-step workflows stay logged in.
3. Process Up to 10,000 URLs in a Single Batch Job
When your pipeline moves from single-page lookups to catalog-wide ingestion, Spicrawl’s asynchronous batch API accepts up to 10,000 URLs per call (and up to 100,000 items across open batch appends) and streams finished records in clean JSON Lines (JSONL) format with granular retry and progress inspection.
4. Hosted MCP Server, Open-Source CLI, TypeScript SDK, and n8n Node
Instead of wiring brittle glue code for every AI assistant, developers can connect compatible coding and workflow agents straight to Spicrawl’s hosted MCP server (https://mcp.spicrawl.com/mcp). Spicrawl ships native support and open-source tooling across:
- AI Coding & Agent Clients: Claude Code, Cursor, Codex CLI, GitHub Copilot / VS Code, Gemini CLI, Windsurf, Cline, and OpenCode.
- Agent & Workflow Frameworks: LangChain document loaders, OpenAI Agents SDK, Dify, and an official n8n node.
- Open-Source Developer Packages: The
@spicrawl/sdkTypeScript/Node.js client, thespicrawlCLI binary (stdout-clean JSONL for shell automation), and agent skill definitions maintained on GitHub and documented in the Spicrawl Docs.
Developer Quickstart: Spicrawl REST API, CLI & MCP Setup
Getting started takes less than two minutes. Generate a workspace token in your Spicrawl dashboard (every workspace includes a free beta tier with 1,000 monthly credits and no credit card required), then call https://api.spicrawl.com/v1/scrape directly—or pass a ProxyTee Unlimited Residential Proxy via Spicrawl’s built-in proxy parameter with zero proxy surcharges.
# Store your Spicrawl bearer token and ProxyTee residential gateway
export SPICRAWL_TOKEN="spicrawl_live_your_token"
export PROXYTEE_GATEWAY="http://pt_user_01:pt_pass_01@gate.proxytee.com:8080"

# Scrape a geo-targeted or protected page into clean Markdown via ProxyTee
curl -sS -i "https://api.spicrawl.com/v1/scrape"   -H "Authorization: Bearer $SPICRAWL_TOKEN"   -H "Content-Type: application/json"   -d '{
    "url": "https://example.com/products/42",
    "response_format": "markdown",
    "proxy": "'"$PROXYTEE_GATEWAY"'",
    "proxy_verify": true
  }'
You can run the exact same bring-your-own-proxy workflow from the spicrawl terminal client or inside Python and TypeScript automation scripts:
import os
import requests

# Route Spicrawl through a dedicated ProxyTee unlimited residential port
resp = requests.post(
    "https://api.spicrawl.com/v1/scrape",
    headers={"Authorization": f"Bearer {os.environ['SPICRAWL_TOKEN']}"},
    json={
        "url": "https://example.com/pricing",
        "response_format": "markdown",
        "proxy": os.environ["PROXYTEE_GATEWAY"],
        "proxy_verify": True,
    },
    timeout=120,
)
resp.raise_for_status()
print("Proxy Source:", resp.headers.get("X-Proxy-Source"))
print("Target Status:", resp.headers.get("X-Target-Status"))
print(resp.text)
To expose live web extraction tools (spicrawl_*) directly to Cursor, Claude Code, or other MCP-compatible assistants, configure the hosted MCP server endpoint in your client settings:
{
  "mcpServers": {
    "spicrawl": {
      "url": "https://mcp.spicrawl.com/mcp",
      "headers": {
        "Authorization": "Bearer spicrawl_live_your_token"
      }
    }
  }
}
How Spicrawl and ProxyTee Power Scalable AI & Web Data Pipelines
Spicrawl supports bring-your-own-proxy (BYOP) natively without adding per-gigabyte proxy markups, and explicitly highlights that residential IPs deliver the highest clearance rates on Cloudflare-protected targets and localized storefronts. That architectural design pairs cleanly with ProxyTee’s unmetered residential network:
| Pipeline Layer | Spicrawl Role | ProxyTee Role |
|---|---|---|
| Page Rendering & Parsing | Converts dynamic HTML/JS into clean Markdown, JSON, text, PDF, or screenshots via /v1/scrape |
Provides clean household ISP IPs across 100+ countries (30M+ residential pool) |
| Anti-Bot & Geo-Targeting | Accepts proxy + proxy_verify and preserves cookies/storage across sessions |
Supports HTTP, HTTPS & SOCKS5 with configurable 3–60 minute auto-rotation |
| High-Volume RAG & Batch Jobs | Queues up to 10,000 URLs per batch call and streams JSONL outputs | Flat-rate ports starting at $29/mo with $0.00/GB unlimited bandwidth |
| AI Agent Connectivity | Hosted MCP server, TypeScript SDK, CLI, LangChain, OpenAI Agents SDK & n8n node | Dual username:password or IP Whitelist auth for serverless & self-hosted agents |
When teams run multi-thousand-page AI, RAG, and LLM ingestion workflows or localized Playwright and Python Requests scrapers, per-GB proxy pricing can quickly outpace compute bills. Routing Spicrawl’s proxy parameter—or your own headless scrapers—through ProxyTee’s unmetered ports keeps bandwidth costs predictable at scale, even when rendering heavy client-side pages.
Ready to Make Website Data Work for Your AI Agents?
Spicrawl brings reliable web extraction directly into the REST APIs, terminal CLIs, workflow builders, and MCP-enabled AI agents developers use every day—so teams spend less time debugging DOM parsers and more time shipping intelligent products.
- Start Scraping Free with Spicrawl: Explore Spicrawl and claim 1,000 free monthly credits (or review the Spicrawl pricing tiers and MCP server setup).
- Power Your Egress with ProxyTee: Pair Spicrawl’s bring-your-own-proxy option with ProxyTee Unlimited Residential Proxy Plans starting at $29/month for truly unmetered bandwidth across 100+ countries, or browse all 18 ProxyTee integration guides.
Frequently Asked Questions
Spicrawl is a developer-focused web scraping and data extraction API that converts any URL into clean Markdown, structured JSON (via autoparse, CSS selectors, or JSON Schema), HTML, plain text, screenshots, or PDFs with optional real-browser JavaScript rendering and session persistence.
Principal infrastructure engineer at ProxyTee specializing in rotating residential proxy networks, SOCKS5/HTTP tunneling, TLS fingerprint mitigation, and distributed data extraction pipelines.